Support our educational content for free when you purchase through links on our site. Learn more
Optimize AI Strategy: Compare Frameworks & Benchmark 🧭


Optimizing AI Strategy with Framework Comparison and Benchmarking starts with a simple rule: choose a framework that fits your business goals, then test real workloads against clear quality, safety, performance, and cost thresholds. No single framework—or model benchmark—can make the decision for you.
We’ve seen teams spend days comparing model leaderboards, only to discover that their biggest performance problem was outdated source data or a workflow employees barely used. The useful question isn’t simply “Which AI scored highest?” It’s “Which approach improves our work, for whom, and under what conditions?”
That’s why a sound strategy pairs business prioritization with responsible-AI governance, representative benchmarks, and ongoing monitoring. A flashy demo may win the room; reproducible evidence helps you decide what deserves to reach production.
Key Takeaways
- Match frameworks to the job: Use strategy frameworks to prioritize investments, risk frameworks to guide oversight, and technical benchmarks to compare systems.
- Benchmark realistic workloads: Test representative tasks, edge cases, and failure conditions—not just vendor demos or public leaderboard prompts.
- Measure more than speed: Combine quality, latency, reliability, safety, adoption, and total cost of ownership.
- Set thresholds before testing: Define success criteria and guardrails upfront to avoid shifting the goalposts after results arrive.
- Evaluate the full workflow: Include data, retrieval, integrations, human review, and user adoption—not only the model.
- Treat benchmarking as continuous: Re-test after material changes and monitor real-world performance after deployment.
Table of Contents
- ⚡️ Quick Tips and Facts
- 🧭 Background: Why AI Strategy Frameworks Need Benchmarking
- How AI strategy evolved from experimentation to measurable outcomes
- What an AI strategy framework does—and what it doesn’t
- 🧩 Core Components of an Effective AI Strategy
- Business goals, use-case prioritization, and value hypotheses
- Data readiness, governance, and responsible AI
- People, operating models, and organizational change
- Technology architecture, platforms, and vendor choices
- 🔎 AI Strategy Frameworks Compared: Criteria, Strengths, and Trade-Offs
- Enterprise and business-transformation frameworks
- Responsible AI and risk-management frameworks
- Maturity models, operating models, and governance frameworks
- Build-versus-buy and cloud-versus-on-premise approaches
- 📊 Benchmarking Methodology: From Baseline to Decision
- Define the decision, scope, and benchmark questions
- Choose representative workloads and test scenarios
- Control variables, repeat tests, and document assumptions
- Set baselines, targets, and acceptance thresholds
- 📏 AI Strategy Metrics and KPIs That Matter
- Business value, productivity, and adoption metrics
- Model quality, reliability, and safety measures
- Latency, throughput, scalability, and availability
- Total cost of ownership, ROI, and time to value
- Governance, compliance, and risk indicators
- 🧪 Model and Application Benchmarking in Practice
- LLM evaluation: accuracy, reasoning, and task completion
- RAG, agents, and end-to-end workflow evaluation
- Traditional machine learning and computer vision benchmarks
- Human evaluation, automated tests, and production feedback
- ⚙️ Infrastructure, Performance, and Compatibility Testing
- GPU, CPU, memory, and accelerator selection
- Cloud, hybrid, and on-premise performance comparisons
- Inference optimization, batching, quantization, and caching
- Energy efficiency, carbon impact, and compute utilization
- 💰 Cost and Commercial Benchmarking for AI Investments
- Model API costs versus self-hosted inference
- Training, deployment, maintenance, and hidden costs
- Vendor pricing, portability, and contract considerations
- Scenario analysis, sensitivity testing, and budget planning
- 🛡️ AI Governance, Security, and Risk Benchmarking
- Privacy, data protection, and intellectual property
- Bias, explainability, robustness, and safety testing
- Regulatory alignment and audit-ready evidence
- Third-party, model, and supply-chain risk
- 🧠 A Step-by-Step AI Strategy Benchmarking Roadmap
- 1. Establish business priorities and success criteria
- 2. Assess current AI maturity and readiness
- 3. Select frameworks and map gaps
- 4. Design a fair, reproducible benchmark
- 5. Pilot, measure outcomes, and validate assumptions
- 6. Scale, monitor, and continuously improve
- 🏢 Industry Applications and Practical Examples
- Healthcare, financial services, retail, and manufacturing
- Public sector, education, and professional services
- Choosing benchmarks for different business contexts
- 🚧 Common Benchmarking Mistakes—and How to Avoid Them
- Comparing unlike workloads or relying on vendor demos
- Optimizing a single metric at the expense of real outcomes
- Ignoring data quality, change management, and ongoing costs
- ✅ Framework Selection Guide: Which Approach Fits Your Organization?
- Recommendations by maturity, risk tolerance, and budget
- A practical framework comparison scorecard
- When to combine frameworks instead of choosing just one
- 🔗 Recommended Links
- ❓ FAQ
- What is AI strategy benchmarking?
- Which AI strategy framework should we use?
- How do we compare AI models fairly?
- Which AI metrics should executives track?
- How often should AI benchmarks be repeated?
- How can smaller organizations benchmark AI on a limited budget?
- 📚 Reference Links
- 🏁 Conclusion
⚡️ Quick Tips and Facts
The short version: An AI strategy framework helps you decide what to build, govern, and scale. Benchmarking checks whether those choices deliver measurable results on your workloads—not just a tidy slide deck.
Our AI researchers and machine-learning engineers at ChatBench.org™ recommend treating framework comparison and benchmarking as one decision process: define your business goal, compare relevant approaches, test against realistic workloads, then track the result over time. For a focused look at evaluation methods, see our guide to whether AI benchmarks can compare the performance of different AI frameworks.
| Quick fact | What it means for your AI strategy |
|---|---|
| There is no universally best framework. | Choose based on your business goals, risk profile, data, skills, and operating constraints. |
| A benchmark is only useful if it resembles production. | Test representative users, data, context lengths, concurrency, and failure conditions. |
| Speed alone is a weak scorecard. | Track quality, latency, reliability, safety, adoption, and total cost together. |
| Public scores are signals, not procurement guarantees. | Validate results on your own infrastructure and software stack before committing. |
| Benchmarking should continue after launch. | Models, workloads, prices, software, and user expectations change. |
| The best result is a business outcome. | A faster model that answers incorrectly—or is ignored by employees—isn’t a win. |
Quick checklist before comparing frameworks:
- ✅ Write down the decision you need the benchmark to support.
- ✅ Select a small set of representative use cases.
- ✅ Define quality and safety thresholds before looking at scores.
- ✅ Compare end-to-end costs, including integration and human review.
- ❌ Don’t choose a framework because it has the longest checklist or the prettiest dashboard.
We’ve seen teams spend weeks debating model names when the real bottleneck was poor retrieval, unclear success criteria, or a workflow no one wanted to use. That’s why this guide starts with strategy and returns to infrastructure later.
🧭 Background: Why AI Strategy Frameworks Need Benchmarking

How AI strategy evolved from experimentation to measurable outcomes
AI adoption often begins with a demo: a chatbot summarizes a document, a model classifies support tickets, or an agent performs a small task. The challenge arrives when someone asks, “What improved—and how do we know?”
That question marks the shift from AI experimentation to AI operating discipline. A pilot can show that a model works under selected conditions. A benchmark helps determine whether it performs consistently, safely, and economically enough for a real workflow.
The NIST AI Risk Management Framework emphasizes managing AI risks throughout the system lifecycle. The OECD AI Principles likewise provide guidance around trustworthy, human-centered AI. Neither is a magic recipe for picking a model; both help organizations structure important questions about impact, accountability, and risk.
A practical AI strategy therefore connects:
- Business intent: What should improve?
- System design: Which data, models, tools, and processes might help?
- Evaluation: How will you test quality, safety, performance, and cost?
- Operations: Who owns monitoring, updates, incidents, and review?
- Evidence: What result justifies continued investment?
This is where AI business applications and AI news meet the less glamorous but essential work of measurement.
What an AI strategy framework does—and what it doesn’t
An AI strategy framework is a structured way to make decisions about AI use cases, capabilities, investment, governance, and deployment. It can help teams avoid isolated experiments and make responsibilities visible.
It is not:
- A guarantee of financial return.
- A universal ranking of vendors or models.
- A substitute for domain expertise or data stewardship.
- A one-time exercise that remains current forever.
- A benchmark dataset, unless it explicitly includes a testing method.
| Tool or concept | Main question it answers | Example |
|---|---|---|
| Strategy framework | What should we pursue, and how should we organize it? | Use-case portfolio and governance model |
| Maturity assessment | How prepared are we to execute? | Data, talent, infrastructure, and process gaps |
| Benchmark | How does a system perform under defined conditions? | Task success, latency, safety, or throughput |
| Pilot | Can the solution work in a bounded setting? | Trial with one team or workflow |
| Production monitoring | Is the deployed system still working as expected? | Quality, drift, availability, and incident tracking |
Frameworks often differ because they solve different problems. A governance model may prioritize oversight and risk controls; a transformation framework may focus on operating changes and value creation; an infrastructure benchmark may measure accelerator performance. Comparing them as if they were identical tools is like comparing a map, a speedometer, and a seat belt. All useful. None interchangeable.
🧩 Core Components of an Effective AI Strategy
Business goals, use-case prioritization, and value hypotheses
Start with a business problem, not a model catalog. “Use generative AI” is a technology intention. “Reduce the time required to resolve routine service requests without increasing escalation errors” is a testable goal.
For each use case, document:
- Target user and workflow: Who will use the system, and where does it fit?
- Current baseline: How long does the process take? What is the current error or rework rate?
- Value hypothesis: What measurable improvement should AI create?
- Failure impact: What happens if the output is wrong, incomplete, or delayed?
- Human role: Who reviews, approves, or overrides the output?
- Adoption signal: How will you tell whether people actually use it?
A simple prioritization score can help organize discussions, but it should not pretend to be a scientific truth machine.
| Evaluation dimension | Useful question | Example signal |
|---|---|---|
| Business value | Does this address an important cost, growth, or service issue? | Time saved, conversion, service quality |
| Feasibility | Are the data and integrations available? | Data access and workflow readiness |
| Risk | Could an error harm people, expose data, or breach policy? | Severity and likelihood of harm |
| Adoption | Will users trust and understand the workflow? | Task completion and repeat usage |
| Reusability | Can components support other use cases? | Shared retrieval, evaluation, or identity services |
Expert tip: Set the intended outcome before testing models. Otherwise, teams often move the goalposts toward whichever model wins a narrow comparison.
Data readiness, governance, and responsible AI
A sophisticated model cannot rescue stale records, conflicting definitions, or access rules that nobody understands. Data readiness is a strategy issue, not merely an engineering cleanup task.
Assess:
- Data provenance, quality, freshness, and representativeness.
- Permissions, retention, privacy, and sensitive-data handling.
- Whether training or retrieval sources can be audited.
- How errors, bias, and harmful outputs will be detected.
- Who is accountable for approvals and remediation.
The NIST AI RMF Playbook provides practical considerations for applying the framework’s governance, mapping, measuring, and managing functions. For organizations operating in the EU, the European Commission’s AI Act overview is a starting point for understanding the regulatory framework; applicability depends on the system and context, so legal advice may be needed.
A useful benchmark should test not only “Does it answer?” but also:
- Does it answer from approved sources?
- Does it decline when it lacks evidence?
- Does it expose or retain sensitive information improperly?
- Does it treat relevant user groups consistently?
- Can the team explain and investigate a failure?
People, operating models, and organizational change
AI strategy changes jobs, handoffs, and accountability. That makes change management part of performance—not a cheerful announcement after deployment.
Define who owns:
- Product outcomes and user feedback.
- Data access and quality.
- Model and application evaluation.
- Security, legal, and risk review.
- Deployment, monitoring, and incident response.
- User training and process redesign.
A central AI team can set reusable standards and infrastructure. Domain teams can supply workflow knowledge and evaluate whether outputs make sense. The strongest model is often federated: shared guardrails, local ownership of use cases.
For more on tool-using systems and their operational implications, explore AI agents and AI automation workflows.
Technology architecture, platforms, and vendor choices
Your architecture determines how easily you can change models, manage data, and compare alternatives. Think beyond the model endpoint:
- Model provider or self-hosted runtime.
- Retrieval, vector search, and source-document pipelines.
- Identity, permissions, and audit logging.
- Evaluation, observability, and feedback capture.
- Orchestration, tools, and human approval steps.
- Data residency, portability, and exit options.
Brands such as Microsoft Azure AI, Google Cloud Vertex AI, Amazon Bedrock, and Databricks Mosaic AI provide enterprise AI capabilities, but platform features do not eliminate the need for independent testing. Compare them using your own workload, governance requirements, integration needs, and operational skills.
🔎 AI Strategy Frameworks Compared: Criteria, Strengths, and Trade-Offs
There is no single framework that covers strategy, responsible AI, organizational maturity, and low-level hardware performance equally well. The practical answer is to choose a primary decision framework and complement it with focused governance and evaluation methods.
| Framework or approach | Best suited to | Strength | Watch-out |
|---|---|---|---|
| NIST AI RMF | Risk-aware AI development and deployment | Lifecycle-oriented risk management guidance | Requires organization-specific implementation |
| OECD AI Principles | High-level trustworthy-AI principles | Useful policy and values reference | Not a technical benchmark or implementation plan |
| ISO/IEC 4201 | AI management systems | Formal management-system approach | Certification and implementation require scope and effort |
| Gartner AI maturity models | Enterprise capability assessment | Helps structure maturity conversations | Methodology and scoring details can depend on the specific model |
| Internal use-case portfolio model | Investment prioritization | Directly ties projects to local objectives | Can become biased or inconsistent without common criteria |
| Technical benchmark suite | Model, platform, or hardware evaluation | Enables repeatable performance comparisons | May miss business fit, risk, and user adoption |
The ISO/IEC 4201 overview describes a management-system standard for organizations that provide or use AI systems. It complements, rather than replaces, workload testing and business-case analysis.
Enterprise and business-transformation frameworks
Enterprise frameworks typically address portfolio choices, capabilities, operating models, and value realization. They are useful when teams need to move beyond scattered proofs of concept.
A good transformation framework should help you answer:
- Which business processes deserve investment first?
- What capabilities can be shared across teams?
- How will benefits be measured and realized?
- Which decisions belong centrally, and which belong to business units?
- How will projects be stopped when evidence is weak?
Trade-off: Broad strategy frameworks can make an organization feel organized without proving that an individual system works. Pair them with task-level evaluation and real workflow pilots.
Responsible AI and risk-management frameworks
Risk frameworks make less glamorous questions hard to ignore: misuse, bias, privacy, security, transparency, and human oversight. The NIST AI RMF organizes its core functions as Govern, Map, Measure, and Manage.
Use risk frameworks to:
- Classify use cases by potential impact.
- Assign ownership and escalation routes.
- Identify foreseeable misuse and failure modes.
- Establish evidence for testing and ongoing monitoring.
- Connect technical safeguards to business and legal responsibilities.
Perspective check: A risk framework may appear to slow delivery, especially during a low-risk prototype. But proportional controls can prevent a fast pilot from quietly becoming a high-impact production system with no owner.
Maturity models, operating models, and governance frameworks
Maturity models help identify capability gaps. They can assess data foundations, talent, infrastructure, governance, process integration, and measurement. Use them to support a roadmap—not to turn maturity scores into a trophy shelf.
A practical maturity review should:
- Define the scope: organization-wide, business unit, or use case.
- Gather evidence, not just self-reported confidence.
- Identify the few gaps that constrain priority use cases.
- Assign owners and deadlines.
- Repeat the assessment when strategy or operating conditions change.
Beware of false precision. A “3.7 out of 5” data maturity score is not useful if no one can explain the evidence behind it.
Build-versus-buy and cloud-versus-on-premise approaches
Build-versus-buy is not simply a contest between “more control” and “less work.” It is a comparison of lifecycle responsibilities.
| Option | Potential benefits | Potential drawbacks | Benchmark focus |
|---|---|---|---|
| Third-party model API | Quick access to capable models; provider handles much of serving | Provider dependency, data terms, changing model behavior | Quality, latency, availability, privacy, cost |
| Managed cloud platform | Integrated security and infrastructure services | Platform coupling and complex service choices | End-to-end workload, governance, portability |
| Self-hosted open-weight model | More control over runtime and deployment | Hardware, tuning, reliability, and security burden | Quality after tuning, utilization, operational effort |
| Hybrid architecture | Flexibility to route workloads by need | More integration and monitoring complexity | Routing accuracy, fallback behavior, total cost |
For self-hosting, compare real deployment options such as NVIDIA NIM, vLLM, and Huging Face Text Generation Inference. The right choice depends on expertise and workload—not on a benchmark headline alone.
📊 Benchmarking Methodology: From Baseline to Decision
Benchmarking is an experiment. Treat it like one: state the question, control what you can, record what you cannot, and avoid pretending a one-off run is definitive.
Define the decision, scope, and benchmark questions
Start with a decision statement such as:
“We will select a system that meets our answer-quality and privacy requirements while reducing average handling time for this workflow.”
Then define:
- System boundary: Model alone, or full application and human workflow?
- Candidates: Which models, frameworks, platforms, or configurations?
- Users and tasks: Who will use it, and what will they ask it to do?
- Constraints: Latency, safety, data residency, availability, budget, or hardware?
- Decision rule: What thresholds must be met, and how will trade-offs be handled?
That first boundary matters. A model-only evaluation might say one candidate is faster. An end-to-end test may show that another retrieves better evidence and saves more staff time.
Choose representative workloads and test scenarios
Build a test set from real or carefully constructed examples. Include ordinary cases, difficult cases, edge cases, and cases where the right answer is “I don’t know.”
For a generative AI assistant, test:
- Typical prompts and common user phrasing.
- Long and short inputs.
- Ambiguous or incomplete requests.
- Requests outside the system’s scope.
- Sensitive data and prompt-injection attempts.
- Different user roles and permission levels.
- Tool failures, retrieval gaps, and unavailable services.
If comparing RAG, fine-tuning, and prompt engineering, the IBM Technology video on RAG vs. fine-tuning vs. prompt engineering can help explain what each technique changes before you design the tests. Keep the test focused on your application: each approach may be suitable for different kinds of problems.
Control variables, repeat tests, and document assumptions
Record the ingredients of every run:
- Model name, version, provider, and date.
- System prompt, decoding settings, and safety configuration.
- Retrieval corpus, embedding model, chunking, and reranking settings.
- Hardware, serving software, batch size, and concurrency.
- Input distribution, test-set version, and evaluator method.
- Warm-up behavior, retries, timeout rules, and failures.
Run tests more than once when the system is nondeterministic or performance varies with load. Report distributions and uncertainty, not just the best observed score.
A benchmark without configuration details is anecdote wearing a lab coat.
Set baselines, targets, and acceptance thresholds
Compare candidates with the current workflow—not just with each other. The baseline might be manual processing, an existing rules engine, or the system already in production.
| Measurement | Baseline | Target | Guardrail |
|---|---|---|---|
| Task success | Existing workflow result | Material improvement | Must not fall on critical cases |
| Response time | Current end-to-end duration | Meets user expectation | Tail latency stays within tolerance |
| Safety | Current incident and review profile | No unacceptable risk | Required refusal and escalation behavior |
| Cost | Current cost per completed task | Sustainable at expected volume | Include support and human review |
| Adoption | Existing workflow usage | Regular, useful adoption | Monitor abandonment and overrides |
A strong acceptance rule combines minimum thresholds with a reasoned trade-off. For example, a model may be acceptable only if it passes safety tests and quality thresholds, after which cost and latency determine the preferred option.
📏 AI Strategy Metrics and KPIs That Matter
A balanced scorecard avoids the classic trap: celebrating a model that is fast, cheap, and confidently wrong. Choose metrics tied to your use case and define how each is measured.
Business value, productivity, and adoption metrics
Measure outcomes near the workflow:
- Time to complete: Including review, corrections, and escalations.
- Task completion rate: Whether users finish the task successfully.
- Rework and error rate: How often outputs require correction.
- Service quality: Resolution, satisfaction, or response consistency.
- Adoption and retention: Whether users return and complete relevant tasks.
- Business impact: Revenue, operating capacity, service access, or risk reduction.
Avoid counting generated text as value. Output volume is not business impact.
Model quality, reliability, and safety measures
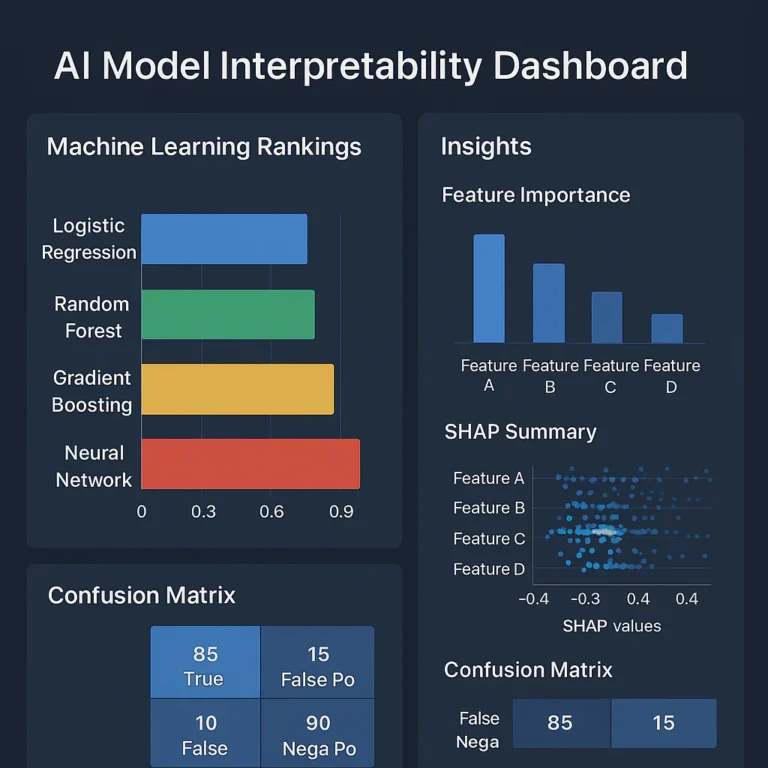
The right quality metric depends on the task. Classification may use precision, recall, and F1; extraction may measure field-level correctness; generation may require expert review, rubric scoring, groundedness, and task completion.
For LM applications, evaluate:
- Correctness and completeness.
- Evidence quality and citation support.
- Relevance and instruction following.
- Hallucination or unsupported-claim rate.
- Safe refusal and escalation behavior.
- Robustness across user groups, formats, and adversarial inputs.
The HELM benchmark from Stanford CRFM provides a framework for evaluating language models across scenarios and metrics. It is a useful reference, but no public benchmark can fully represent your proprietary workflow.
Latency, throughput, scalability, and availability
For interactive applications, measure end-to-end latency and its distribution, including the slow tail. Report:
- Time to first token, where relevant.
- Total response time.
- Tokens per second or requests per second.
- Concurrency and queueing behavior.
- Error, timeout, and retry rates.
- Availability and recovery behavior.
Average latency can hide a miserable user experience. A system with a reasonable average but frequent slow responses may be worse than a slightly slower system with consistent performance.
Total cost of ownership, ROI, and time to value
Track costs across the full lifecycle:
- Model inference or API usage.
- Training, fine-tuning, and evaluation.
- Data preparation and storage.
- Integration, security, and governance.
- Monitoring, maintenance, and incident response.
- Human review, correction, and change management.
A useful unit might be cost per successfully completed task, not cost per call or token. That measure accounts for retries, failures, and human effort.
Be cautious with ROI projections. State assumptions about usage, labor savings, quality changes, and adoption; then test them in a pilot. The NIST AI RMF is a useful reminder that risk and trustworthiness are part of responsible system performance, not optional footnotes.
Governance, compliance, and risk indicators
Governance indicators can include:
- Percentage of systems with named owners and documented intended use.
- Coverage of risk assessments and pre-deployment testing.
- Incident response time and recurrence.
- Access-control and data-retention compliance.
- Completion of required human reviews.
- Time to detect model or data changes that affect performance.
Use these to identify problems early, not to produce a dashboard that no one acts on.
🧪 Model and Application Benchmarking in Practice
LLM evaluation: accuracy, reasoning, and task completion
A useful LM benchmark uses task-specific examples and explicit scoring rubrics. Generic question-answer accuracy may be relevant for one application and nearly useless for another.
A practical evaluation loop:
- Build a held-out set of representative tasks.
- Write scoring criteria before running candidate systems.
- Use deterministic checks where possible.
- Send subjective or high-impact cases to qualified reviewers.
- Analyze errors by category, not just aggregate score.
- Re-test after model, prompt, or infrastructure changes.
Automated model graders can help scale reviews, but they can have their own biases and blind spots. Validate graders against human judgments, and use human review for high-impact or ambiguous outputs. The OpenAI Evals repository and EleutherAI Language Model Evaluation Harness are examples of evaluation tooling; inspect their fit and assumptions before adopting them.
RAG, agents, and end-to-end workflow evaluation
A RAG system can produce a fluent answer while retrieving the wrong document. An agent can call a tool successfully but take an unnecessary or risky route. Evaluate the whole workflow, not just the final sentence.
For RAG, assess:
- Retrieval recall and ranking quality.
- Answer correctness and source support.
- Freshness and permission-aware retrieval.
- Appropriate abstention when evidence is missing.
- Citation accuracy and traceability.
For agents, add:
- Task success across multiple steps.
- Tool-selection accuracy and argument validity.
- Recovery from errors and unavailable tools.
- Permission boundaries and action confirmation.
- Cost, latency, and unnecessary action rate.
The RAGAS documentation describes evaluation concepts for retrieval-augmented generation. Use its metrics as starting points, then verify that the evaluation aligns with your domain and users.
Traditional machine learning and computer vision benchmarks
For supervised systems, benchmark the task and the deployment context. A fraud model, a visual inspection system, and a demand forecast need different metrics and different error costs.
Consider:
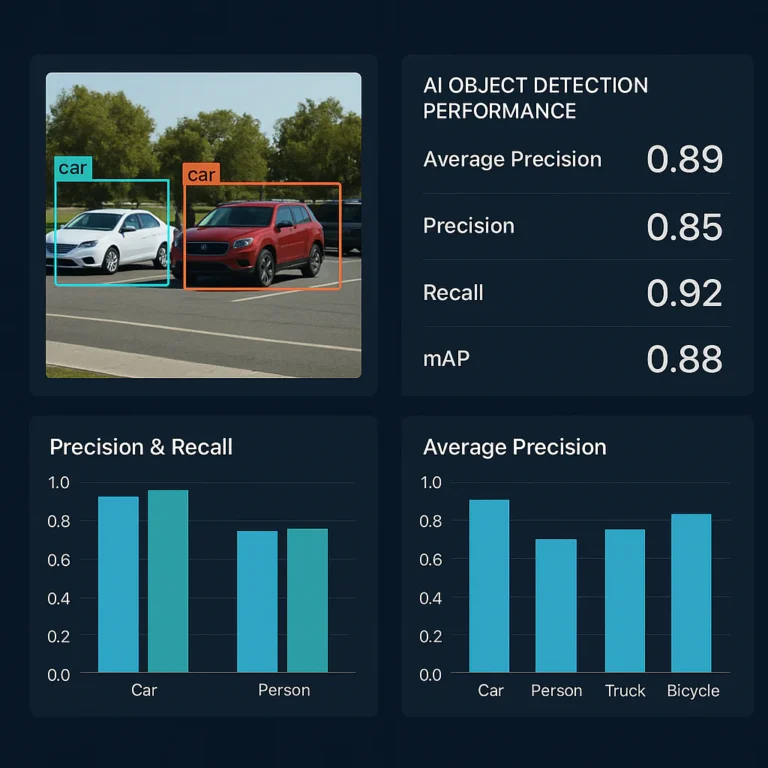
- Precision and recall at operational thresholds.
- Class imbalance and rare-event performance.
- Calibration and confidence behavior.
- Performance by relevant subgroups.
- Data drift and concept drift.
- Real-world latency and human review burden.
The MLPerf benchmarks provide standardized comparisons across selected machine-learning workloads and systems. They can inform infrastructure decisions, but they do not establish that a system will perform well on your data or business task.
Human evaluation, automated tests, and production feedback
Use a mix of evaluators:
| Evaluation method | Useful for | Limitation |
|---|---|---|
| Unit and regression tests | Stable behaviors and known failure cases | Cannot cover every real-world input |
| Programatic metrics | Large-scale, repeatable scoring | May reward a proxy instead of the desired outcome |
| Expert review | Domain nuance and high-impact decisions | Costly and can vary between reviewers |
| User feedback | Workflow usefulness and trust | Can be noisy or skewed toward vocal users |
| Production monitoring | Real operating behavior | Detects issues after deployment unless paired with safeguards |
We recommend maintaining a golden test set for regressions and a separate stream of newly sampled production cases. That keeps the benchmark from becoming a museum of yesterday’s prompts.
⚙️ Infrastructure, Performance, and Compatibility Testing
GPU, CPU, memory, and accelerator selection
Hardware selection is a workload decision. A GPU’s published peak throughput does not tell you what your application will deliver after memory limits, communication overhead, software kernels, and serving behavior enter the picture.
For infrastructure benchmarking, record:
- Accelerator model and configuration.
- Memory capacity and bandwidth.
- Interconnect and multi-node topology.
- Precision and numerical format.
- Software drivers, compilers, and serving stack.
- Power, utilization, temperature, and throttling.
- Workload quality, throughput, and latency together.
The MLCommons organization publishes standardized benchmark programs; vendors such as NVIDIA and AMD publish product and platform information. Treat vendor specifications as a starting point, then test the intended configuration.
Cloud, hybrid, and on-premise performance comparisons
A cloud instance, a managed API, and an on-premise cluster differ in more than raw speed. Compare deployment options across:
- Data location and governance.
- Provisioning and scaling.
- Network and storage performance.
- Availability and support model.
- Portability and exit strategy.
- Operational staffing and maintenance.
- Real cost at expected utilization.
A fair comparison uses the same model version, workload, quality threshold, and traffic assumptions whenever possible. If a provider manages the serving stack, record the available configuration details and acknowledge what cannot be controlled.
For broader infrastructure coverage, see AI infrastructure.
Inference optimization, batching, quantization, and caching
Inference performance often changes substantially with serving configuration. Test optimizations one at a time where possible:
- Batching: Can improve throughput, but may increase latency.
- Quantization: Can reduce memory use and improve efficiency, with possible quality trade-offs.
- Caching: Can reduce repeated work, but requires careful handling of freshness and sensitive data.
- Speculative decoding: May improve response speed under suitable conditions.
- Kernel and runtime choices: Can change performance by hardware and model.
- Prompt and context design: Can reduce unnecessary computation.
For serving tools, compare real deployments using projects such as vLLM and SGLang, alongside vendor-supported options when relevant. The key is not to declare one runtime the winner universally; it’s to validate the combination you plan to run.
Energy efficiency, carbon impact, and compute utilization
Power efficiency belongs in the scorecard when energy, cooling, capacity, or sustainability affects the decision. Track useful work per unit of energy, not just peak power draw.
Useful measures include:
- Energy per completed task or generated token.
- Accelerator utilization and idle capacity.
- Power under representative load.
- Cooling and facility constraints.
- Workload scheduling and utilization patterns.
Low energy per token is not automatically low total impact if a system produces more unnecessary work. Pair energy metrics with task success and usage.
💰 Cost and Commercial Benchmarking for AI Investments
Model API costs versus self-hosted inference
Managed APIs reduce infrastructure responsibilities; self-hosting can improve control and offer different economics at scale. Neither wins automatically.
Compare:
- Cost per successful task at realistic usage.
- Peak and off-peak demand.
- Engineering and operations effort.
- Reliability and support requirements.
- Data handling and governance.
- Quality after any model adaptation.
For cloud options, examine official documentation from Amazon Bedrock, Azure AI, and Vertex AI. Do not compare token rates alone: different models may need different prompt lengths, retry rates, or human corrections.
Training, deployment, maintenance, and hidden costs
A project’s cost can include more than compute:
- Data cleaning, labeling, and permissions.
- Integration and workflow redesign.
- Security testing and compliance work.
- Monitoring and evaluation infrastructure.
- Model updates and regression testing.
- Human review, support, and incident handling.
- Vendor transition and data-exit work.
A useful total-cost model separates fixed costs, usage-sensitive costs, and risk-related costs. Test high and low utilization scenarios, since an architecture that looks attractive at high utilization may be inefficient when demand is sporadic.
Vendor pricing, portability, and contract considerations
Commercial comparisons should include contract terms as well as technical scores. Review:
- Data retention and training-use terms.
- Service availability and support commitments.
- Model versioning and change notifications.
- Usage limits, throttling, and overage rules.
- Auditability and access to logs.
- Portability, export, and termination provisions.
Have procurement, security, legal, and engineering teams review the same assumptions. A technically excellent system can still be a poor fit if its terms conflict with your obligations or make a future exit impractical.
Scenario analysis, sensitivity testing, and budget planning
Build at least three scenarios:
| Scenario | Assumptions to test |
|---|---|
| Low adoption | Limited usage, slower learning, fixed integration costs remain |
| Expected adoption | Planned workflow coverage and normal demand patterns |
| High demand | Increased concurrency, scaling limits, support load, and usage costs |
Test how conclusions change when quality, volume, review rates, or latency assumptions move. If a small change in assumptions flips the preferred option, the decision is sensitive and deserves a pilot or contract flexibility.
🛡️ AI Governance, Security, and Risk Benchmarking
Privacy, data protection, and intellectual property
Benchmark the data path, not only the model response. Check what enters prompts, where logs are stored, who can access outputs, and how long records persist.
Questions to resolve:
- Is personal or confidential data sent to an external service?
- Are retention and deletion controls clear?
- Can access be limited by user role?
- Are source materials and model outputs handled under suitable terms?
- Can sensitive information be removed from logs and test sets?
The UK Information Commissioner’s Office guidance on AI and data protection is a useful reference for organizations considering data protection implications. Requirements vary by jurisdiction and use case.
Bias, explainability, robustness, and safety testing
Test performance across relevant populations and conditions. Aggregate accuracy can hide a poor experience for a subgroup or a brittle response to a slight change in wording.
A robust test plan includes:
- Subgroup analysis where appropriate and lawful.
- Adversarial and out-of-distribution inputs.
- Prompt injection and unsafe tool-use tests.
- Confidence, refusal, and escalation behavior.
- Explanation or evidence requirements.
- A process for investigating and correcting harmful failures.
No single “bias score” captures fairness in every context. Select measures that reflect the decision, affected people, and applicable obligations.
Regulatory alignment and audit-ready evidence
Keep records that show what was evaluated, by whom, on which version, and with what outcome. Evidence may include:
- Intended use and system boundaries.
- Data and model documentation.
- Test sets, rubrics, and results.
- Risk assessments and approvals.
- Change logs and monitoring records.
- Incident reports and corrective actions.
The EU AI Act portal and NIST AI RMF can support planning, but organizations should assess legal applicability with qualified counsel.
Third-party, model, and supply-chain risk
Third-party dependencies include model providers, datasets, libraries, plugins, and infrastructure. Track:
- Version and provenance.
- Vulnerability and update procedures.
- Data-use and licensing terms.
- Security review and access boundaries.
- Fallback options if a service changes or becomes unavailable.
A strong strategy avoids hidden single points of failure. Maintain an inventory and decide in advance what happens if the preferred model, provider, or tool is no longer available.
🧠 A Step-by-Step AI Strategy Benchmarking Roadmap
1. Establish business priorities and success criteria
- Choose a workflow with a clear owner and meaningful outcome.
- Document the current process and baseline performance.
- Define the users, constraints, and failure consequences.
- Set minimum quality, safety, latency, and cost thresholds.
- Agree on what evidence will justify scaling—or stopping.
2. Assess current AI maturity and readiness
Review data, skills, infrastructure, governance, integration capacity, and user readiness. Gather evidence from systems and workflows rather than relying only on stakeholder confidence.
Prioritize the gaps that block the selected use case. You do not need to perfect every capability before running a responsible pilot.
3. Select frameworks and map gaps
Choose frameworks by purpose:
- Use a strategy or portfolio method to prioritize work.
- Use a risk framework to structure governance.
- Use a maturity assessment to identify capability gaps.
- Use a technical benchmark to compare system performance.
- Use a business scorecard to track realized outcomes.
Map overlaps and missing responsibilities. If every framework names a review function but nobody owns it, the organization has a governance gap, not a documentation problem.
4. Design a fair, reproducible benchmark
- Select representative tasks and edge cases.
- Freeze the test-set version and scoring rubric.
- Record every model, prompt, runtime, and configuration.
- Define repeats, warm-up, concurrency, and timeout behavior.
- Include quality, safety, latency, cost, and human effort.
- Decide in advance how results will be compared.
For hardware or infrastructure selection, tools such as MLPerf can provide standardized context. For application selection, your own workload remains essential.
5. Pilot, measure outcomes, and validate assumptions
Run a bounded pilot with real users and safeguards. Compare results with the baseline, collect corrections and feedback, and inspect failure patterns.
Ask:
- Did the system improve the target outcome?
- Did users complete tasks more effectively?
- Did review or escalation workload rise?
- Were safety and privacy assumptions upheld?
- Did actual cost and latency match the estimate?
A pilot that fails to meet thresholds is useful evidence. It has saved you from scaling a weak assumption.
6. Scale, monitor, and continuously improve
Before scaling, assign owners for monitoring, change approvals, incidents, and retraining or reconfiguration. Keep a regression suite and evaluate after material changes to models, prompts, data, retrieval, tools, or infrastructure.
This is where the narrative comes full circle: the “best” framework is the one that helps your organization make better decisions repeatedly, not the one that wins a one-day comparison.
🏢 Industry Applications and Practical Examples
Healthcare, financial services, retail, and manufacturing
| Industry | Example use case | Benchmark priorities |
|---|---|---|
| Healthcare | Clinical documentation support | Accuracy, privacy, clinician review, workflow time |
| Financial services | Customer support or document analysis | Compliance, consistency, traceability, error severity |
| Retail | Product discovery and service assistance | Relevance, conversion quality, response speed, escalation |
| Manufacturing | Visual quality inspection or maintenance support | Defect recall, false alarms, uptime, integration reliability |
The same model can have different acceptability across contexts. A minor error in product-description drafting is not equivalent to a false negative in a safety-critical inspection workflow. Benchmark thresholds should reflect consequences.
Public sector, education, and professional services
In public services and education, benchmarks may need to account for accessibility, language coverage, transparency, and equitable access. In professional services, confidentiality, source traceability, and expert review may dominate.
Use case-specific test data and involve the people who will rely on the system. A technically impressive demo can miss local terminology, policy, or process realities.
Choosing benchmarks for different business contexts
Match the test to the decision:
- Customer-facing assistant: task completion, groundedness, latency, escalation quality.
- Internal knowledge search: retrieval quality, permissions, source freshness, user trust.
- Document processing: field accuracy, exception handling, throughput, auditability.
- Forecasting: error by horizon, calibration, stability, operational usefulness.
- Developer assistant: accepted suggestions, defect rates, time saved, security checks.
- Autonomous agent: task success, action safety, tool reliability, recovery behavior.
If you want the benchmark to influence a real business decision, include the people who own the workflow—not only the people who build the model.
🚧 Common Benchmarking Mistakes—and How to Avoid Them
Comparing unlike workloads or relying on vendor demos
A result is only comparable when the task, data, configuration, and scoring method are sufficiently aligned. Vendor demos can reveal features, but curated examples are not neutral tests.
Do instead: Run a shared evaluation set, record configuration details, and validate on your own system before purchase or rollout.
Optimizing a single metric at the expense of real outcomes
A low-latency model can increase rework. A high-throughput system can perform poorly on difficult cases. A low cost per token can conceal high human-review costs.
Do instead: Use a scorecard with thresholds for quality and risk, then compare cost and performance among candidates that meet them.
Ignoring data quality, change management, and ongoing costs
Models are often blamed for failures caused by stale content, poor access controls, unclear process ownership, or insufficient user training.
Do instead: Test the full workflow, name owners, measure adoption, and include operations and review costs in the business case.
✅ Framework Selection Guide: Which Approach Fits Your Organization?
Recommendations by maturity, risk tolerance, and budget
| Situation | Recommended emphasis | Why |
|---|---|---|
| Early experiments, limited governance | Small use-case portfolio plus basic risk assessment | Prevents pilots from becoming ownerless |
| Several teams deploying AI | Shared evaluation standards and federated governance | Enables consistency without centralizing every decision |
| High-impact or regulated workflows | Formal risk management, strong audit evidence, human oversight | Makes accountability and evidence explicit |
| Infrastructure or model procurement | Reproducible workload benchmark plus deployment validation | Tests actual performance and operating fit |
| Mature, scaled AI program | Continuous monitoring, portfolio reviews, and lifecycle governance | Keeps decisions current as systems change |
A smaller organization can start with lightweight processes. “Lightweight,” however, should mean proportionate and documented, not “we’ll remember what we tested.”
A practical framework comparison scorecard
Score candidate frameworks against your requirements, using a documented scale and evidence. Avoid adding every possible criterion; choose the ones that affect the decision.
| Criterion | Weighting question |
|---|---|
| Business alignment | Does it connect AI choices to measurable organizational goals? |
| Risk coverage | Does it help identify and manage relevant harms? |
| Technical evaluation | Does it specify repeatable tests or integrate with them? |
| Operational fit | Can your teams actually implement and maintain it? |
| Auditability | Can you show how decisions were reached? |
| Flexibility | Can it adapt to different use cases and changing models? |
The scorecard should structure discussion—not replace judgment. If two frameworks score similarly, choose the one your teams can maintain and combine it with targeted tools for missing capabilities.
When to combine frameworks instead of choosing just one
Combining approaches is often sensible because each has a different job:
- Strategy framework: Selects priorities and operating model.
- Risk framework: Structures governance and oversight.
- Maturity model: Identifies organizational gaps.
- Technical benchmark: Measures a specific system or workload.
- Business scorecard: Checks whether value was realized.
The combination only works when responsibilities are clear. Otherwise, you get three overlapping committees, four spreadsheets, and one lonely production owner wondering who approves the release.