LM-as-a-Judge Framework for Enterprise: 10 Essentials 🧑 ⚖️

Featured image for LM-as-a-Judge Framework for Enterprise 10 Essentials

Video: LLM as a Judge: Scaling AI Evaluation Strategies. The strongest LLM-as-a-judge framework for enterprise combines a clear evaluation rubric, validation against human reviewers, and ongoing monitoring. Treat the AI judge as a fast, scalable reviewer—not unquestionable ground truth—and it…

16 Key NLP Model KPIs: What Really Measures Performance? 🧠

Featured image for 12 Essential KPIs for Evaluating NLP Models in 2025

Video: Key Performance Indicators for Quality – Measuring What Matters in TQM (Chapter 43). The key performance indicators for evaluating natural language processing models are task-specific quality metrics—such as precision, recall, F1, BLEU, ROUGE, or retrieval scores—balanced with fairness, robustness,…

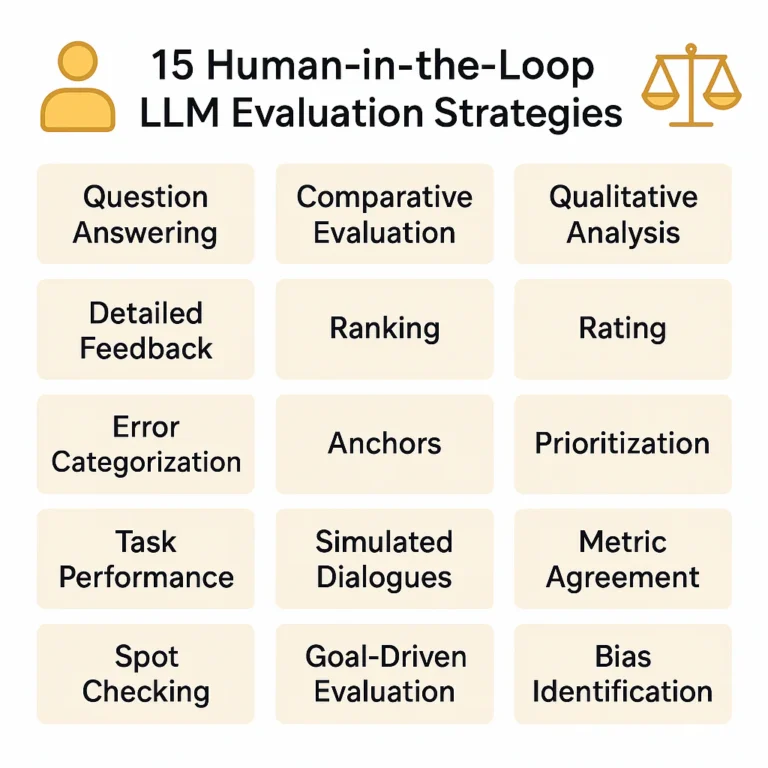
15 Human-in-the-Loop LM Evaluation Strategies 🧑 ⚖️

Featured image for 15 Human-in-the-Loop LM Evaluation Strategies

Video: What is Human In The Loop with AI? How HITL Shapes AI Systems. Human-in-the-loop LM evaluation strategies work best when people handle nuanced, uncertain, and high-risk judgments while automated checks screen routine cases. Combine clear rubrics, representative examples, calibrated…