Support our educational content for free when you purchase through links on our site. Learn more
How AI Benchmarks Shape Business Strategy and Edge 🚀

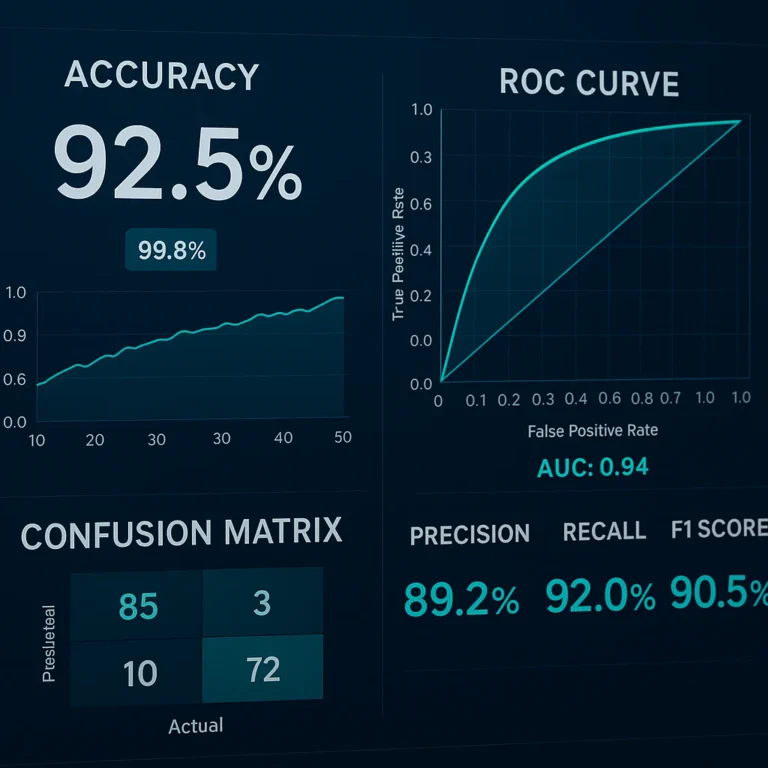
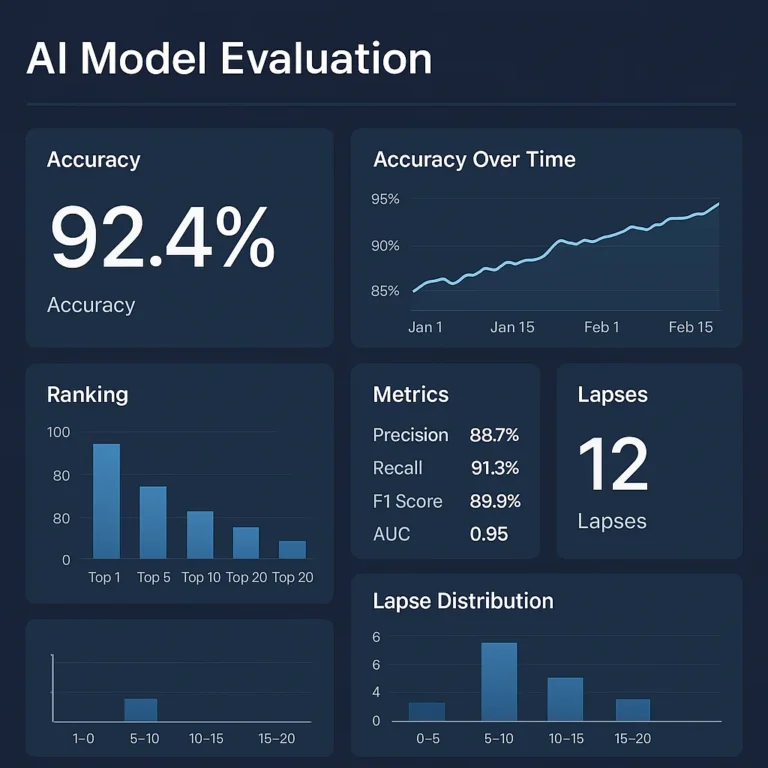
How do AI benchmarks impact the development of AI-driven business strategies and competitive edge? They help businesses compare AI systems, uncover where each model excels or struggles, and make better choices about what to build, buy, test, and deploy. But a leaderboard score isn’t a strategy: the real advantage comes from measuring performance on your own tasks, data, risks, and business goals.
Imagine two companies choosing an AI assistant. One picks the model with the flashiest public score; the other tests how accurately it handles its customer questions, how often people need to correct it, and how much time it saves. The second company may not have the top-ranked model—but it could make the smarter investment.
That distinction matters because AI results can shift with the task, evaluation method, and model version. We’ll explain how to turn benchmarks into practical decisions, where comparisons mislead, and how to use evidence to build a lasting competitive edge. For a useful starting point on keeping evaluations current, see our guide on how often AI benchmarks should be updated.
Key Takeaways
- Use benchmarks to inform strategy, not dictate it. Public scores are useful signals; business-specific tests show whether a model works for your workflows.
- Measure outcomes alongside model performance. Track accuracy, speed, reliability, safety, operating cost, and impact on business goals.
- Compare models fairly. Use consistent tasks, data, settings, and evaluation methods—and document what you tested.
- Treat benchmark results as snapshots. Models, products, and evaluation methods change, so reassess regularly.
- The competitive edge comes from execution. The strongest advantage often comes from matching the right AI capability to proprietary data, effective processes, and human oversight.
Table of Contents
- ⚡️ Quick Tips and Facts: AI Benchmarks, Business Strategy, and Competitive Edge
- 🧭 Background: How AI Benchmarking Became a Strategic Business Tool
- 🔍 What AI Benchmarks Measure—and What They Don’t
- Model performance, capability, safety, and cost metrics
- Public benchmarks, private evaluations, and real-world tests
- 📊 How AI Benchmarks Shape Business Strategy and Competitive Advantage
- From benchmark scores to business outcomes
- How benchmark insights improve strategic decision-making
- When benchmark leadership does—and doesn’t—create an edge
- 🏭 Industries Where AI Benchmarking Can Move the Needle
- Retail, pricing, and demand forecasting
- Healthcare, finance, and other high-stakes sectors
- Marketing, customer service, and software development
- ✅ Key Benefits of AI Benchmarking for Business Leaders
- 🧪 Benchmark Types and Frameworks Worth Knowing
- General-purpose model benchmarks
- Task-specific and industry benchmarks
- Safety, robustness, and responsible AI evaluations
- 🛠️ Tools and Technologies for AI Benchmarking
- Model evaluation platforms and leaderboards
- Cloud providers, open-source tools, and internal test suites
- 🚀 A Step-by-Step Framework for Using Benchmarks in AI Strategy
- 1. Define business goals and success metrics
- 2. Choose relevant benchmarks and comparison groups
- 3. Test models with representative business data
- 4. Translate results into build, buy, or partner decisions
- 5. Pilot, monitor, and update evaluations over time
- 🏢 Building an AI Benchmarking Program Across Your Organization
- Roles for executives, data teams, and business owners
- Benchmark governance, documentation, and review cycles
- 📈 Real-World Examples of Benchmark-Informed AI Strategy
- Retail: comparing AI for pricing and inventory decisions
- Healthcare: evaluating accuracy, safety, and workflow fit
- Digital marketing: measuring content and campaign performance
- ⚠️ Common AI Benchmarking Challenges—and Practical Fixes
- Benchmark saturation, data leakage, and score chasing
- Bias, reproducibility, and apples-to-oranges comparisons
- Privacy, security, compliance, and intellectual property
- 💡 AI Benchmarking Best Practices: Do’s and Don’ts
- 💰 Costs, ROI, and How Small Businesses Can Get Started
- 🔮 Emerging Trends in AI Benchmarks and Competitive Strategy
- Agent, multimodal, and domain-specific evaluations
- Benchmarking efficiency, reliability, and total cost of ownership
- What AI benchmarking may look like over the next decade
- ❓ Frequently Asked Questions About AI Benchmarks and Business Strategy
- How do AI benchmarks improve business decision-making?
- Do higher benchmark scores always mean a better model for my company?
- Can small businesses use AI benchmarks effectively?
- How should businesses protect data during model evaluations?
- How often should an organization reassess AI models?
- 🌐 Explore More in AI-Powered Business Insights
- Conclusion
- Recommended Links
- Reference Links
Table of Contents
- ⚡️ Quick Tips and Facts: AI Benchmarks, Business Strategy, and Competitive Edge
- 🧭 Background: How AI Benchmarking Became a Strategic Business Tool
- 🔍 What AI Benchmarks Measure—and What They Don’t
- Model performance, capability, safety, and cost metrics
- Public benchmarks, private evaluations, and real-world tests
- 📊 How AI Benchmarks Shape Business Strategy and Competitive Advantage
- From benchmark scores to business outcomes
- How benchmark insights improve strategic decision-making
- When benchmark leadership does—and doesn’t—create an edge
- 🏭 Industries Where AI Benchmarking Can Move the Needle
- Retail, pricing, and demand forecasting
- Healthcare, finance, and other high-stakes sectors
- Marketing, customer service, and software development
- ✅ Key Benefits of AI Benchmarking for Business Leaders
- 🧪 Benchmark Types and Frameworks Worth Knowing
- General-purpose model benchmarks
- Task-specific and industry benchmarks
- Safety, robustness, and responsible AI evaluations
- 🛠️ Tools and Technologies for AI Benchmarking
- Model evaluation platforms and leaderboards
- Cloud providers, open-source tools, and internal test suites
- 🚀 A Step-by-Step Framework for Using Benchmarks in AI Strategy
- 1. Define business goals and success metrics
- 2. Choose relevant benchmarks and comparison groups
- 3. Test models with representative business data
- 4. Translate results into build, buy, or partner decisions
- 5. Pilot, monitor, and update evaluations over time
- 🏢 Building an AI Benchmarking Program Across Your Organization
- Roles for executives, data teams, and business owners
- Benchmark governance, documentation, and review cycles
- 📈 Real-World Examples of Benchmark-Informed AI Strategy
- Retail: comparing AI for pricing and inventory decisions
- Healthcare: evaluating accuracy, safety, and workflow fit
- Digital marketing: measuring content and campaign performance
- ⚠️ Common AI Benchmarking Challenges—and Practical Fixes
- Benchmark saturation, data leakage, and score chasing
- Bias, reproducibility, and apples-to-oranges comparisons
- Privacy, security, compliance, and intellectual property
- 💡 AI Benchmarking Best Practices: Do’s and Don’ts
- 💰 Costs, ROI, and How Small Businesses Can Get Started
- 🔮 Emerging Trends in AI Benchmarks and Competitive Strategy
- Agent, multimodal, and domain-specific evaluations
- Benchmarking efficiency, reliability, and total cost of ownership
- What AI benchmarking may look like over the next decade
- ❓ Frequently Asked Questions About AI Benchmarks and Business Strategy
- How do AI benchmarks improve business decision-making?
- Do higher benchmark scores always mean a better model for my company?
- Can small businesses use AI benchmarks effectively?
- How should businesses protect data during model evaluations?
- How often should an organization reassess AI models?
- 🌐 Explore More in AI-Powered Business Insights
- Conclusion
- Recommended Links
- Reference Links